By Swapnil Upganlawar
Curiosity,
made useful.
I’m Swapnil Upganlawar. I help engineering and product leaders turn AI pilots into dependable work, with clear ownership and costs they can defend. Model Fieldnotes is where I share the experiments, practical analysis, and engineering decisions behind that work.
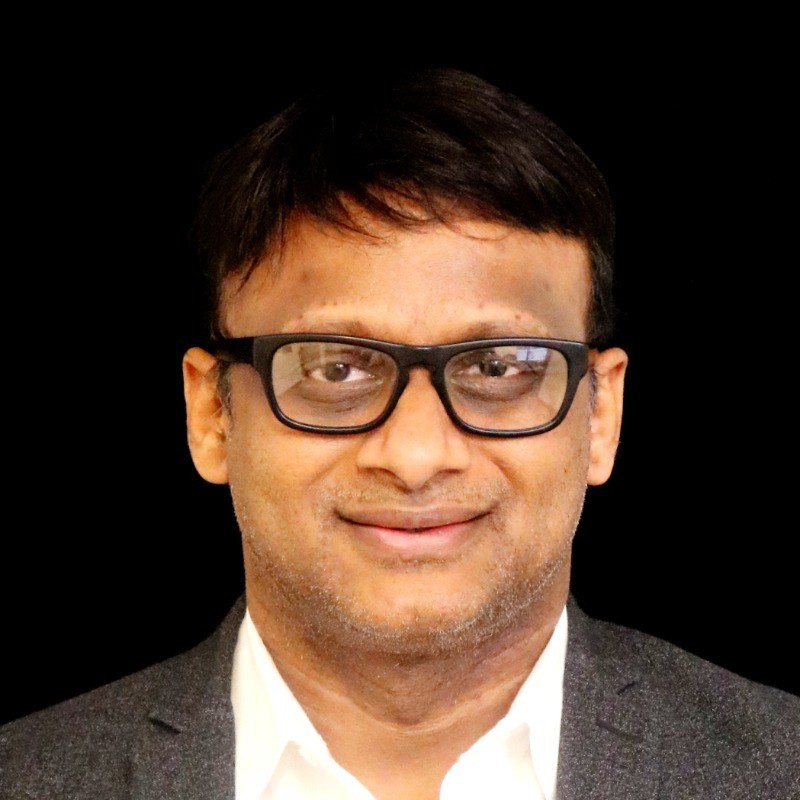
A little about me
I’ve spent more than two decades turning research into useful products, founding software ventures, and leading engineering teams. My work spans generative AI, enterprise search, retrieval, personalization, and machine learning platforms. I enjoy connecting technical depth with product judgment: understanding what a system can do, and deciding what is worth building with it.
I hold an MBA from Wharton and an MS in Bioinformatics from Carnegie Mellon. My curiosity spans the engineering, economics, and governance of AI: how agents behave, how to evaluate models, what useful outcomes cost, and where the evidence leaves room for doubt.
I’m a contributor to Forbes Technology Council, which I joined in September 2026. My focus is enterprise AI, agent reliability, and engineering leadership.
My article, How Enterprise AI Agents Earn Autonomy, was published in Forbes Technology Council on .
From research to enterprise AI
Research and entrepreneurship. At Carnegie Mellon, I worked on NIH- and NSF-funded research using machine learning and patient gene-expression data to explore personalized leukemia treatment. I also founded Organized Campus and served as founder and CTO of nomoreTMI, a platform that used algorithms to reduce information overload from social networks.
Enterprise platforms. At Managed Objects and Novell, I built business service management, monitoring, and analytics software for financial and government institutions. At CEB, I led work on its core member-facing platform, the CEB On The Go mobile product, and personalization. At Gartner, I led machine learning initiatives across business functions, alongside data governance, experimentation, and A/B testing capabilities.
AI at Amazon and AWS. At Amazon, I led AI-powered collaboration, productivity, and knowledge-management experiences serving 1.3 million employees worldwide. My work at AWS has included the Amazon Q general-availability launch and communication connectors, indexing, and retrieval systems for enterprise generative AI.
That experience informs the questions I explore here: how to move from a promising idea to a dependable system, evaluate the outcome, and understand the cost of delivering it.
Conversations beyond the fieldnotes
On October 3, 2026, I joined the technology panel at Wharton’s MBA for Executives 50th Anniversary & Reunion in Philadelphia. We discussed AI adoption, cultural and leadership shifts, governance, guardrails, trust, cost, data foundations, and working backwards from customer problems. As a WEMBA Class 43 graduate, it was a meaningful opportunity to exchange perspectives with the alumni community.
Read my reflections from the paneland see the photograph from the discussion.
Three questions guide the work
Reliability. Will the agent complete the task correctly? The Agent Reliability Fieldbook makes failure mechanisms visible through simulations, with explicit limits.
Economics. What does a useful outcome actually cost? I’m interested in the whole task: tools, retries, verification, and the work left behind when an attempt fails.
Engineering judgment. What should we automate, and under what controls? Useful evaluations connect technical behavior with the product decision a team needs to make.
These questions connect to a wider view of how AI changes products, teams, and business decisions. In What changes when AI can do the work?, I set out that perspective, the evidence behind it, and what would change my mind.
A place to work things out
A useful starting point is the retry experiment: 100 intended operations, 20 acknowledgements deliberately lost after commit, and two service ledgers to inspect. The runnable code, recorded observations, and limitations are published together. It is a controlled software fixture, not a measurement of real-model reliability.
In Leadership & Organizations, I explore how generative AI changes management, team design, and the work of specialists. The aim is to connect research and reputable analysis with decisions about delegation, development, incentives, and accountability.
The work here connects three things: open-source applications you can use, research you can inspect, and practical explanations you can challenge.
Agent Explainer is the first project: an interactive lab for understanding agent failures. The fieldnotes explore the surrounding decisions, from retry behavior and model evaluation to cost and governance.
This is an independent personal project. The writing represents the perspective of Model Fieldnotes, and does not speak for an employer, vendor, or research institution.
Editorial principles
- Follow the evidence. Link to original papers and official documentation. Distinguish source findings from interpretation.
- Name the limits. A simulation teaches a mechanism. A measured experiment supports a claim within its tested conditions. Neither is a universal model ranking.
- Show the work. Reproduced experiments should include their setup, model versions, prompts, dates, and limitations.
- Keep the dates visible. Pricing, model capabilities, and regulation change. Articles show their publication and source-review dates.
- Correct in the open. Substantive corrections receive an update date and explanation on the article.
- Be clear about assistance. AI assists research, drafting, and software development here. Assistance is not independent validation; readers can inspect the cited evidence.
Follow or contribute
Read signed notes, guides, and research through my writing feed or include automated briefings with the combined feed. Follow swapupg on GitHub, or suggest a correction or a question. Contributions that make an explanation clearer are as welcome as code.
Questions & corrections
Found something that needs a second look? Contact me through LinkedIn with the page link, the statement in question, and a supporting source. Reading suggestions and questions are welcome too. Substantive corrections are explained on the affected page.